Blog
Uptime and AI agent monitoring guides for agencies and SaaS teams
Practical guides on website, API and AI agent monitoring, white-label status pages, incident response and client reporting.
Guides by topic
Agencies and MSPs
Monitor every client site, report uptime to clients, and run client incidents without alert chaos.
- Black Friday Monitoring for Agency Client Sites: A Portfolio Playbook
- Agency Alert Fatigue in Website Monitoring: Research, Root Causes, and Smart Alert Grouping
- Agency Incident Response Playbook: How To Handle Client Website Outages Without Chaos
- Client Reporting for Agencies: Uptime Reports That Prove Value Each Month
- Website Monitoring for Agencies: How To Cover Client Sites Without Alert Chaos
- MSP SLA Reporting for Uptime Monitoring: QBR Metrics Clients Actually Care About
- MSP Uptime Monitoring Playbook: Multi-Tenant Operations Without Alert Fatigue
- White-Label Status Pages for Agencies: Reduce Churn During Incidents
Incident response and status pages
What to do in the first minutes of an outage and how to keep customers informed while you fix it.
Uptime and synthetic monitoring
What to monitor first, how to cut alert noise, and why synthetic checks catch what pings miss.
- Why SMBs Leave Website Monitoring Tools: Research on Setup Friction and Plain-English Diagnostics
- Uptime Monitoring for Small Teams: Reduce Alert Fatigue Without Missing Real Incidents
- Uptime Monitoring: A Practical Playbook for Uptime Reliability and Business Growth
- Website and API Uptime Monitoring for Lean Teams: What to Monitor First
- Why Uptime Monitoring Is Important for SEO (and How It Helps Rankings)
- How Synthetic Monitoring Helps (and Why It Is Important)
- Global Website Uptime Monitoring with PingAlert – Fast, Reliable, and Noise-Free
AI agent monitoring
Synthetic reliability checks for AI agents and workflows, from availability to output quality.
Holiday readiness
An 8-part series on preparing for peak traffic, from third-party outages to unexpected load.
- Holiday Capacity Readiness: Quotas, Connection Limits and Rate Limits Before Black Friday
- Holiday Change Freeze: How to Ship Safely During Peak Season
- Holiday On-Call, Runbooks and Incident Communication: Staffing the Peak
- After the Holiday Peak: Post-Incident Reviews and Near-Miss Analysis
- Holiday Reliability Readiness: The Peak-Season Playbook for SRE, DevOps, Platform and Product Teams
- When Third-Party Providers Fail at Peak: Holiday Dependency Readiness
- Unexpected Holiday Traffic: Load Testing, Waiting Rooms and Graceful Degradation
- Holiday Website Monitoring Checklist: Catch Outages Before Customers Do
Outage reports and comparisons
Quarterly outage analysis and side-by-side comparisons of uptime monitoring tools.
- Better Stack Alternative for Agencies: Client Workspaces, Branded Pages and Predictable Cost
- Pingdom Alternative for Agencies: Client Separation, Status Pages and Plan Fit
- StatusCake Alternative for Agencies: Workspaces, Status Pages and Terms Compared
- UptimeRobot Alternative for Agencies: What to Compare Before You Switch
- PingAlert vs UptimeRobot vs Better Stack vs Pulsetic: Best Uptime Monitoring Platform for Modern Teams
- Q2 2026 Reliability Report: What Cloud, Hosting, AI, and Identity Outages Taught Teams
- April 2026 SaaS Outages Agencies Should Have Monitored
- Q1 2026 Infrastructure Reliability Report: Major Outages, Trust Gaps, and Why Third-Party Monitoring Matters
- PingAlert vs Site24x7: What Changes for Uptime-Focused Teams
Latest posts
Better Stack Alternative for Agencies: Client Workspaces, Branded Pages and Predictable Cost
Better Stack vs PingAlert for agencies: responder pricing, white-label status page add-ons, client separation and a safe one-week migration plan.
Black Friday Monitoring for Agency Client Sites: A Portfolio Playbook
Holiday readiness across a client portfolio: tier clients by revenue risk, set per-client freezes, template monitoring, staff on-call and report after peak.
Holiday Capacity Readiness: Quotas, Connection Limits and Rate Limits Before Black Friday
Find the ceilings before peak traffic does: cloud quotas, autoscaling caps, database connection limits, rate limits, queue throughput and restore-tested backups.
Holiday Change Freeze: How to Ship Safely During Peak Season
Plan a holiday change freeze that works: set and announce dates, define critical fixes and approvers, require tested rollbacks, and use feature flags as kill switches.
Try PingAlert free for 14 days
Put reliable monitoring into practice
Start monitoring critical websites and APIs, then keep your team informed when reliability changes.
No credit card required. No automatic charge.
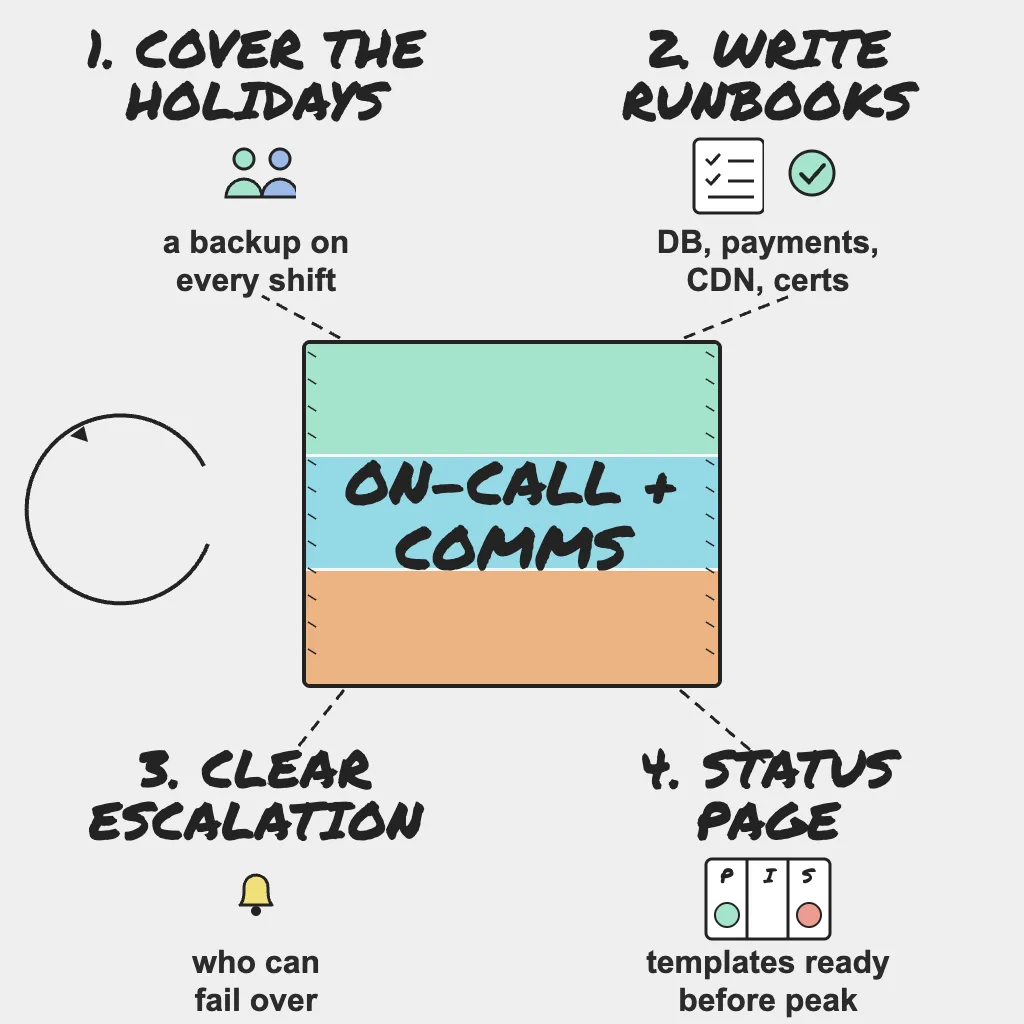
Holiday On-Call, Runbooks and Incident Communication: Staffing the Peak
Plan holiday on-call with backups, write runbooks for likely failures, agree who can fail over, and prepare status page updates before Black Friday.
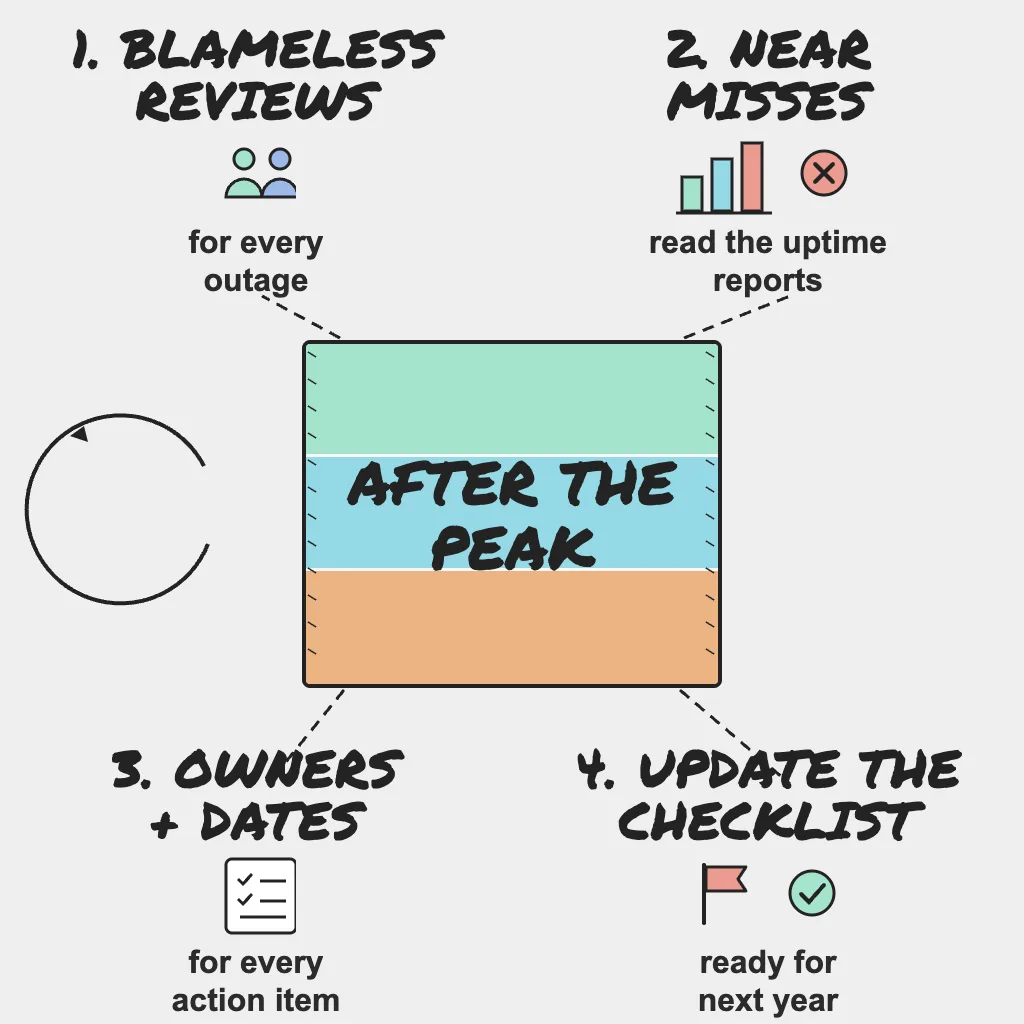
After the Holiday Peak: Post-Incident Reviews and Near-Miss Analysis
Run blameless reviews for every holiday outage, mine uptime and response-time data for near misses, assign owned action items and unwind the freeze safely.
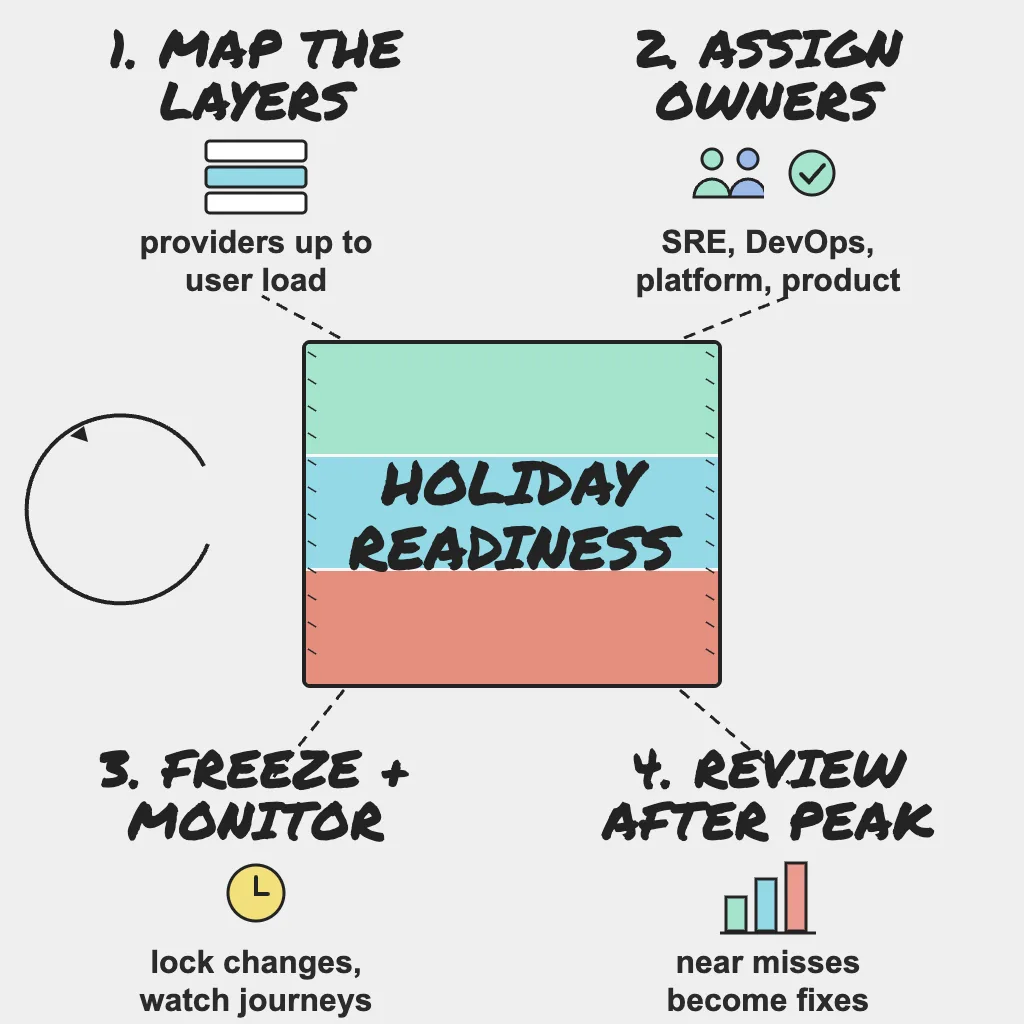
Holiday Reliability Readiness: The Peak-Season Playbook for SRE, DevOps, Platform and Product Teams
A peak-season reliability playbook: a 6-week timeline, a layer-by-layer readiness map from providers to user load, and who owns what across SRE, DevOps, Platform and Product.
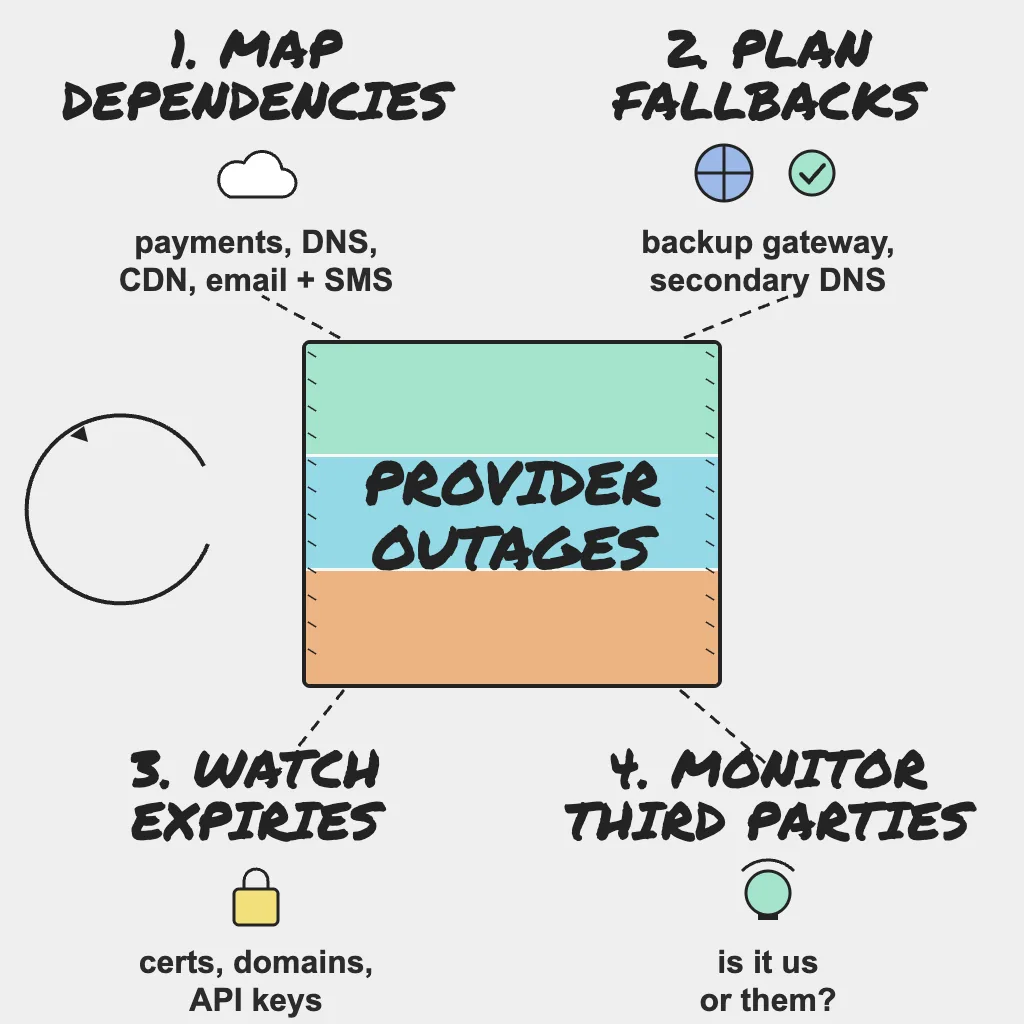
When Third-Party Providers Fail at Peak: Holiday Dependency Readiness
Prepare for third-party outages before Black Friday: map dependencies, decide what checkout does when each fails, test fallbacks, and audit everything that expires.
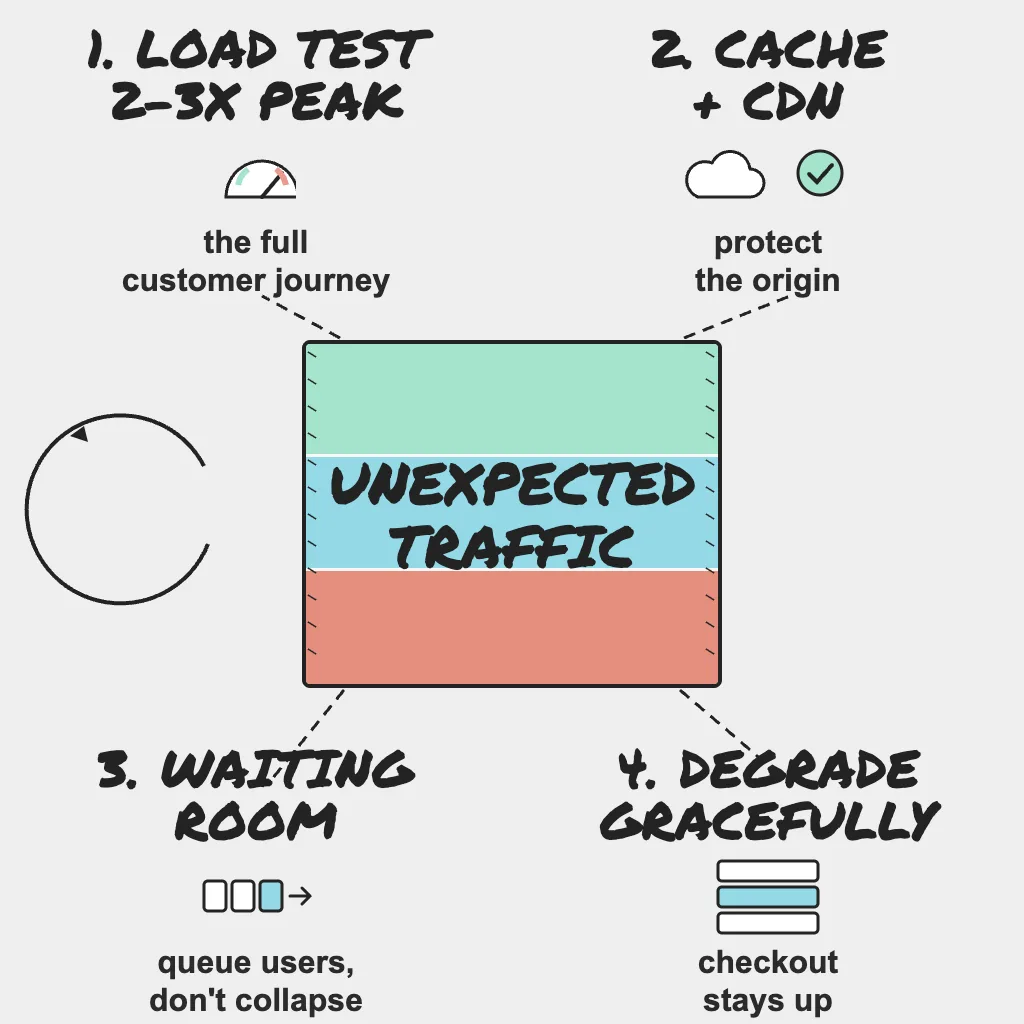
Unexpected Holiday Traffic: Load Testing, Waiting Rooms and Graceful Degradation
Load test the full checkout journey at 2 to 3x last year's peak, plan for traffic you did not forecast, and decide in advance what your site sheds first.
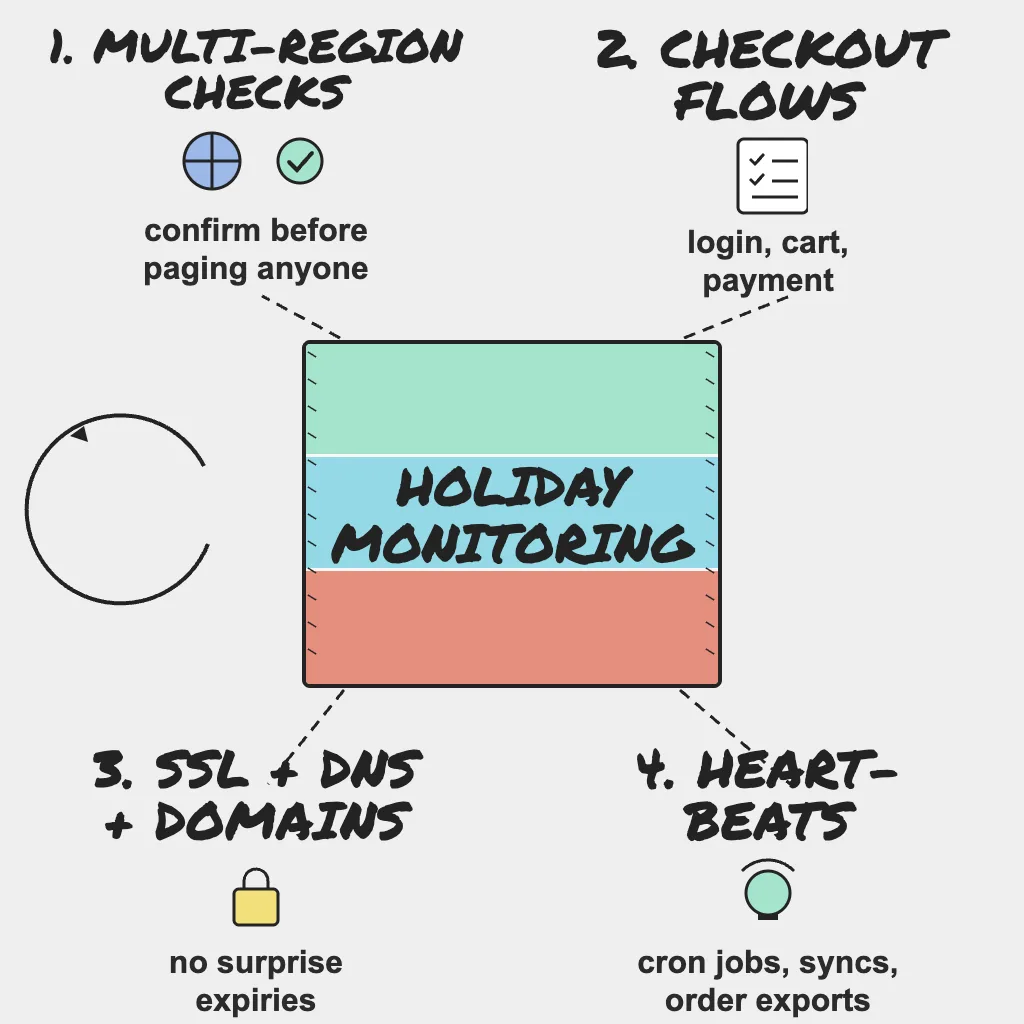
Holiday Website Monitoring Checklist: Catch Outages Before Customers Do
Avoid holiday downtime with this website monitoring checklist. Learn what to test, monitor and alert on before Black Friday so you catch outages first.
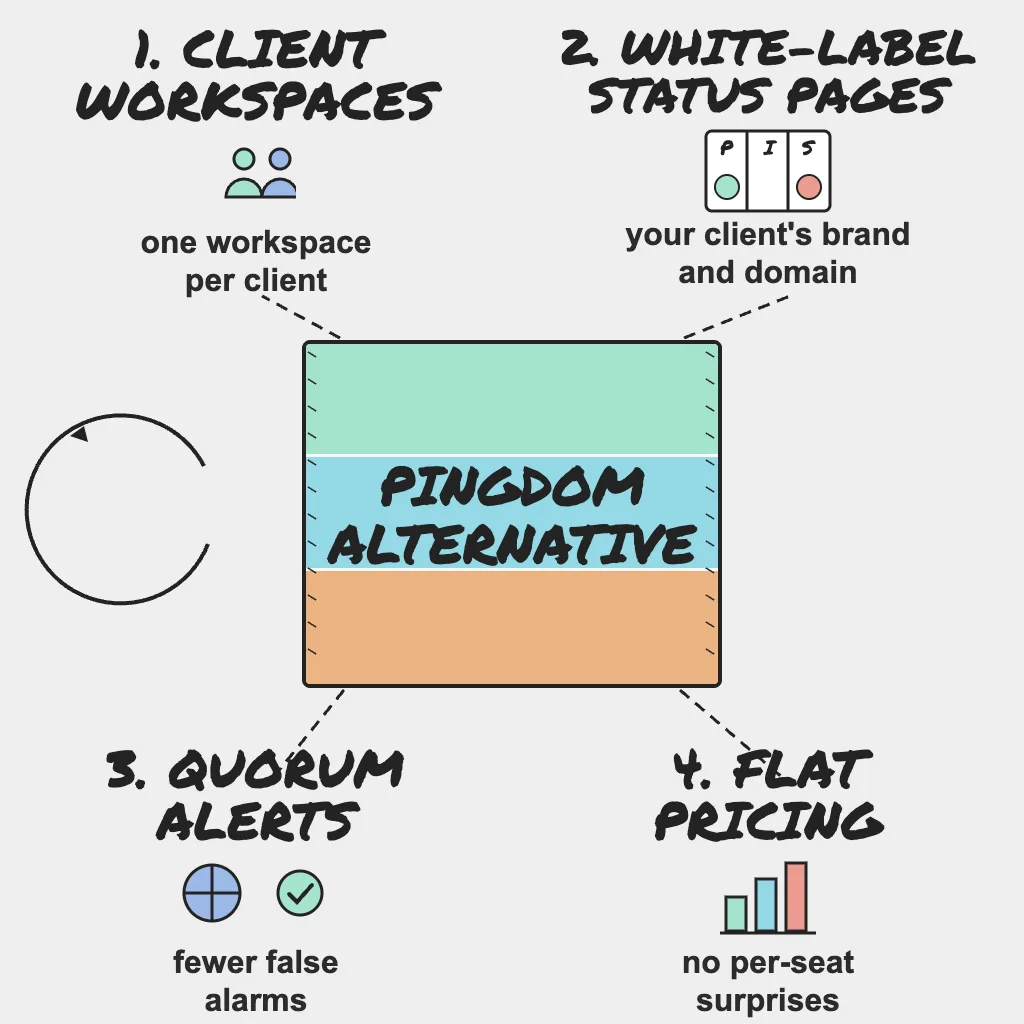
Pingdom Alternative for Agencies: Client Separation, Status Pages and Plan Fit
Pingdom vs PingAlert for agencies: client separation, branded status pages, check coverage, pricing shape and a one-week plan to switch safely.
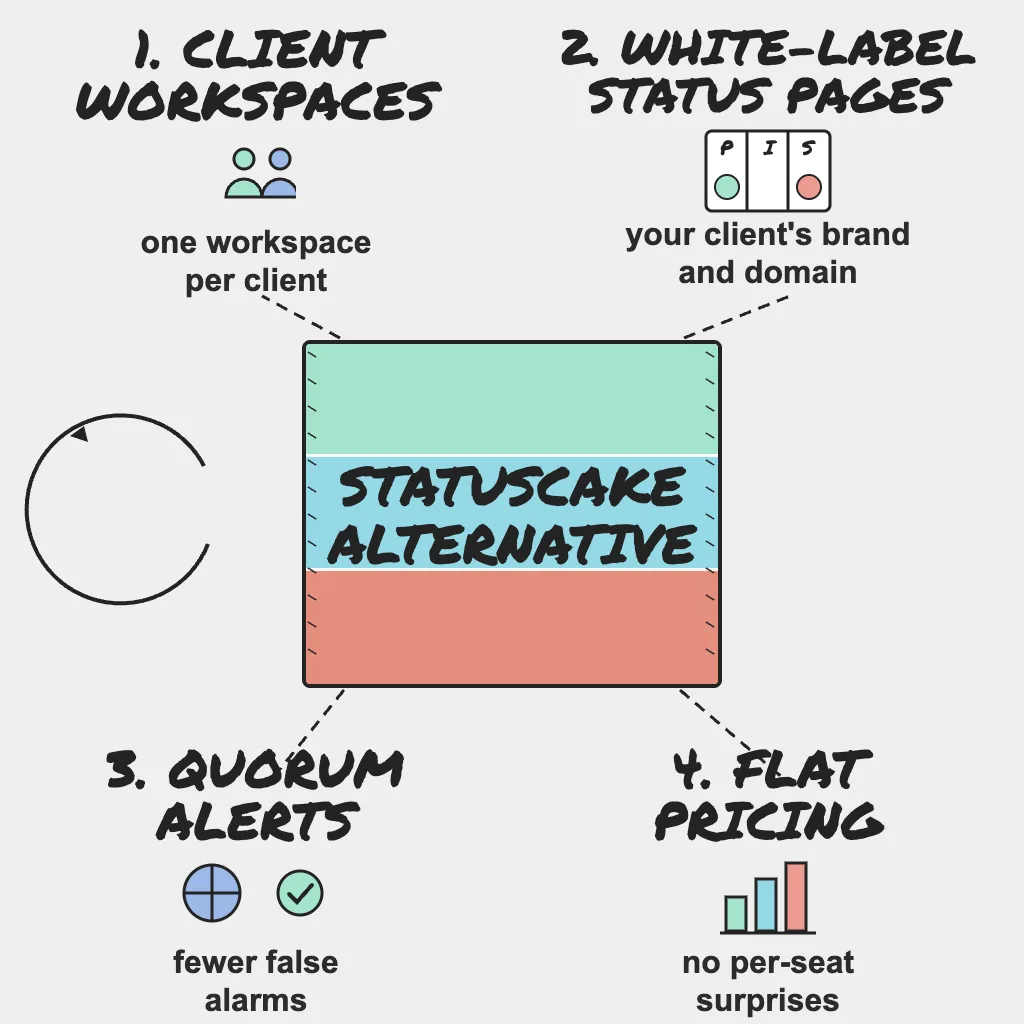
StatusCake Alternative for Agencies: Workspaces, Status Pages and Terms Compared
StatusCake vs PingAlert for agencies: white-label reports, status page plans, client separation, authorized-use terms and a one-week switch plan.
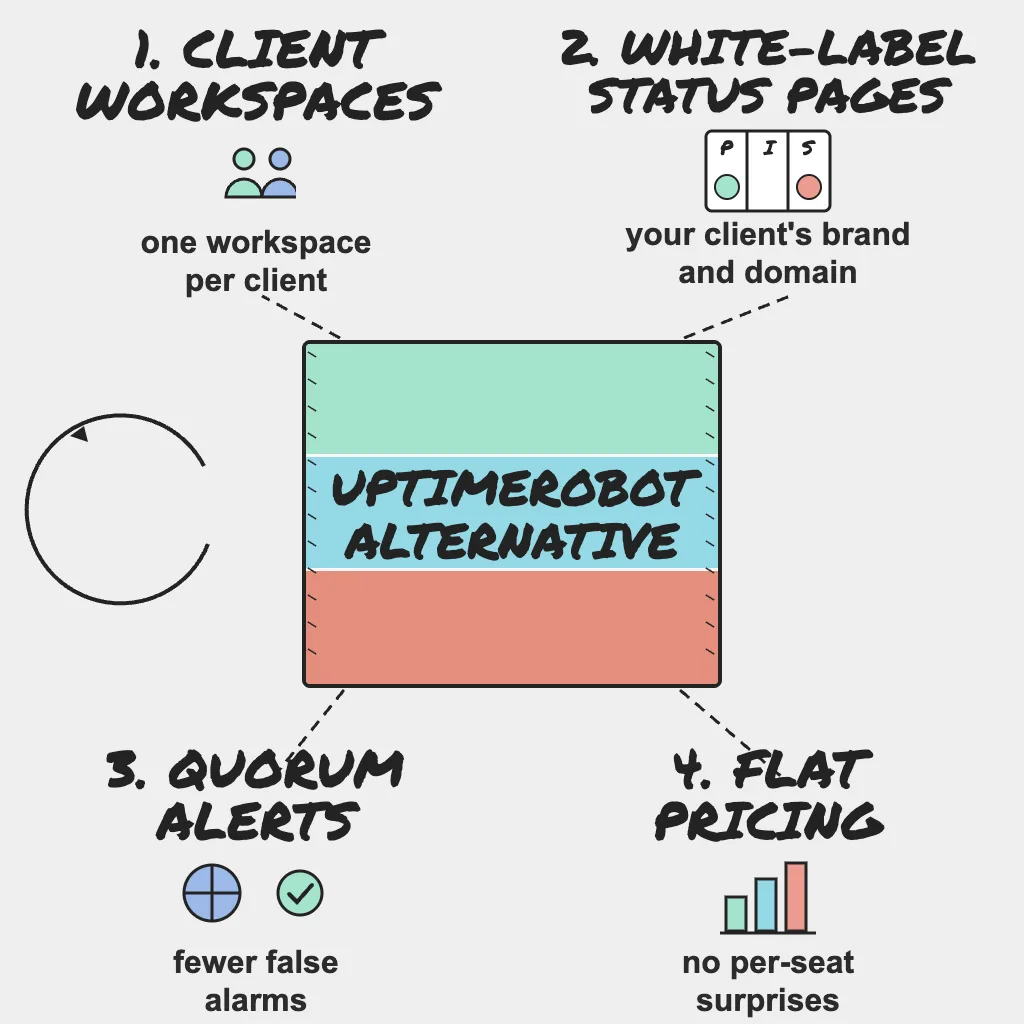
UptimeRobot Alternative for Agencies: What to Compare Before You Switch
UptimeRobot vs PingAlert for agencies: client separation, white-label status pages, pricing, rebranding terms and a one-week plan to switch safely.
AI Agent Monitoring: Synthetic Reliability Checks for AI Workflows
Learn how synthetic AI-agent monitoring helps teams test availability, answer quality, security behavior, and usage cost before customers notice failures.
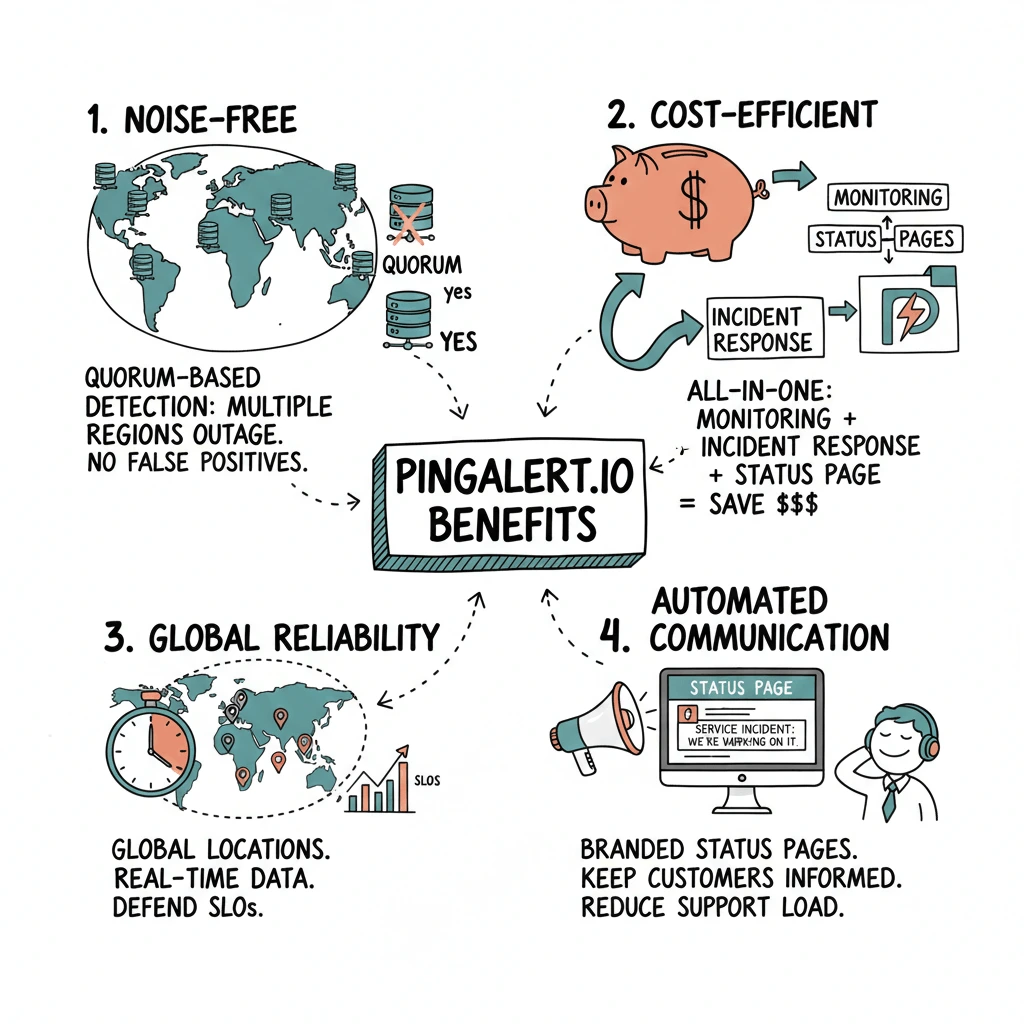
PingAlert vs UptimeRobot vs Better Stack vs Pulsetic: Best Uptime Monitoring Platform for Modern Teams
A practical comparison of PingAlert, UptimeRobot, Better Stack, and Pulsetic for teams choosing an uptime monitoring platform with alerting, incident response, status pages, and customer communication.
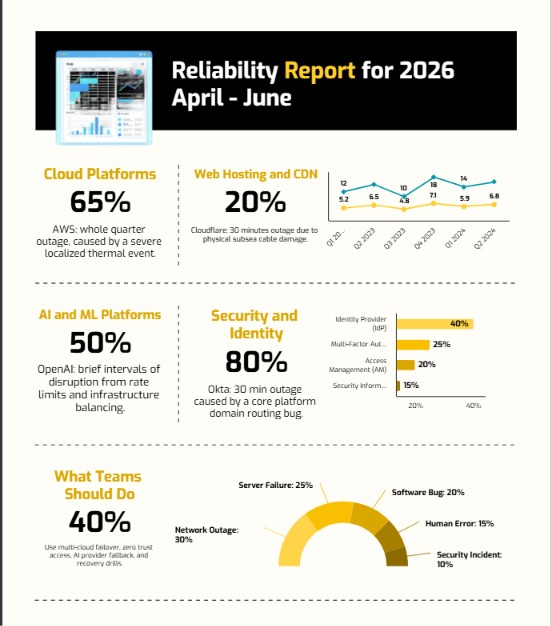
Q2 2026 Reliability Report: What Cloud, Hosting, AI, and Identity Outages Taught Teams
A concise Q2 2026 reliability recap covering cloud, hosting, AI, and identity outages, plus the monitoring and communication changes teams should make next.
April 2026 SaaS Outages Agencies Should Have Monitored
An agency-focused breakdown of the April 2026 SaaS outages that affected delivery workflows, client communication, ecommerce operations, and vendor triage.
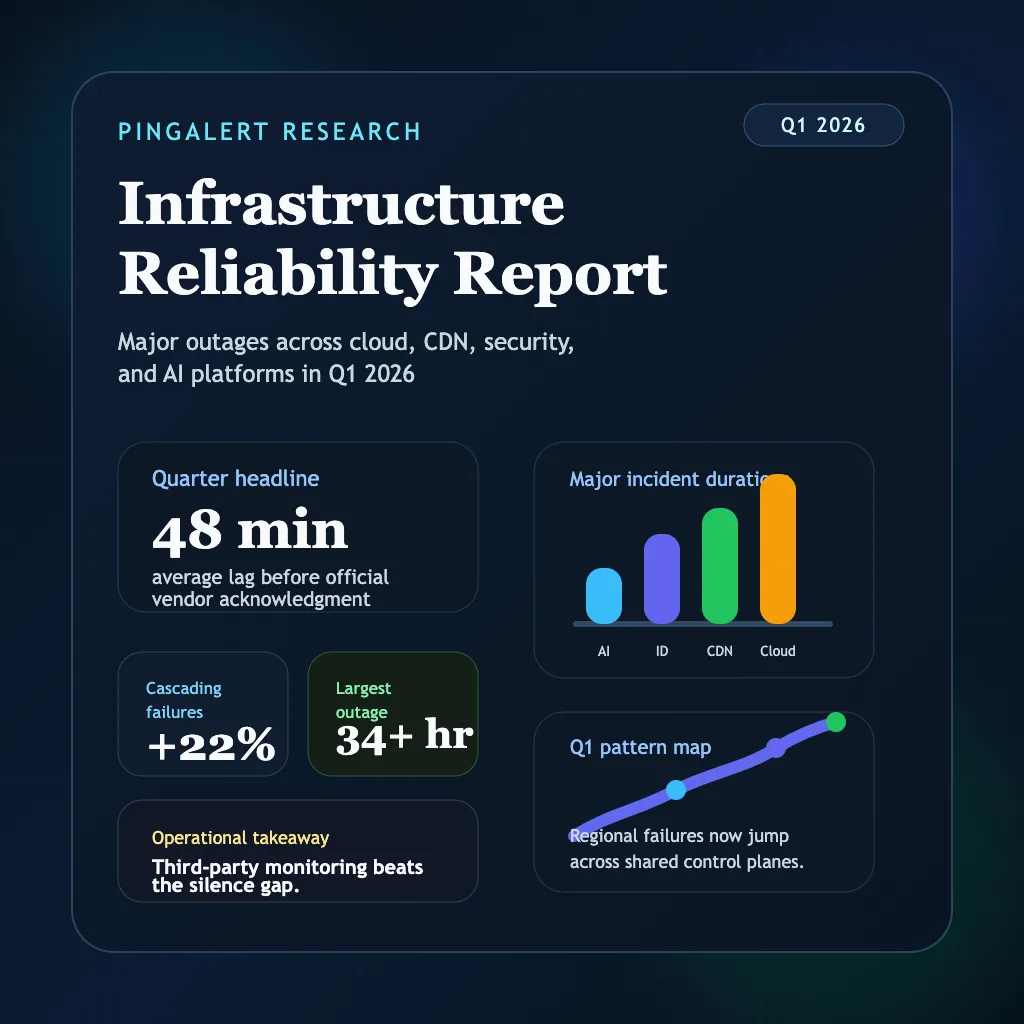
Q1 2026 Infrastructure Reliability Report: Major Outages, Trust Gaps, and Why Third-Party Monitoring Matters
A structured Q1 2026 outage report covering cloud, CDN, security, and AI platform incidents, plus the operational lessons teams should act on next.
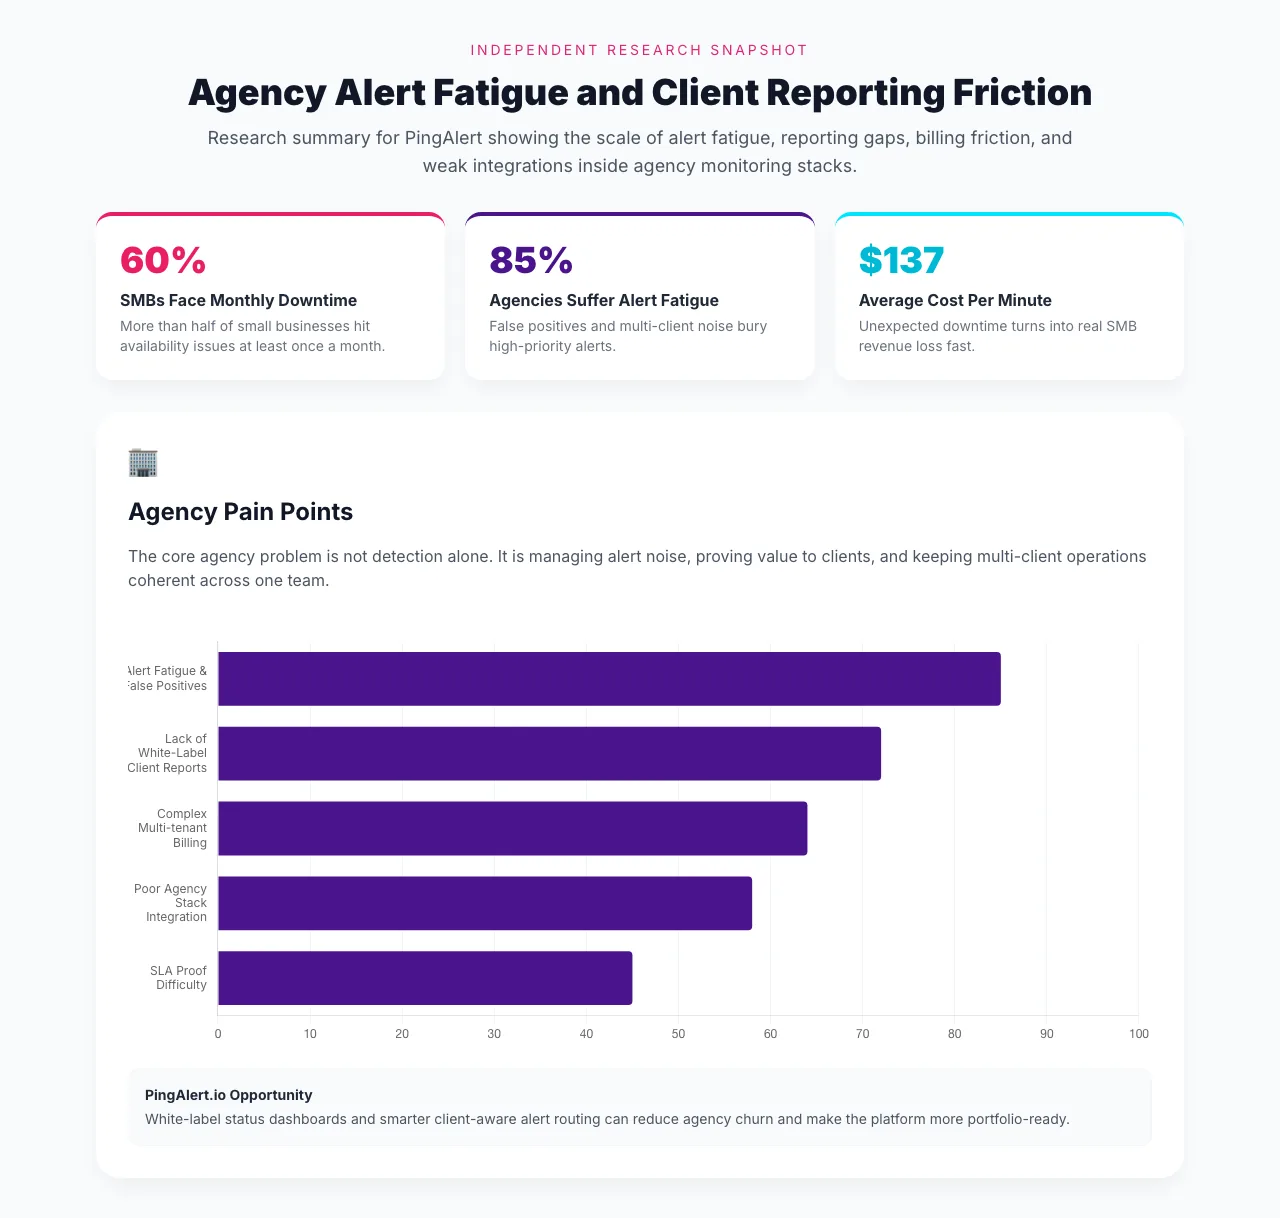
Agency Alert Fatigue in Website Monitoring: Research, Root Causes, and Smart Alert Grouping
Independent research shows agency monitoring teams are hit hardest by alert fatigue, weak client reporting, billing complexity, and fragmented workflows across client portfolios.
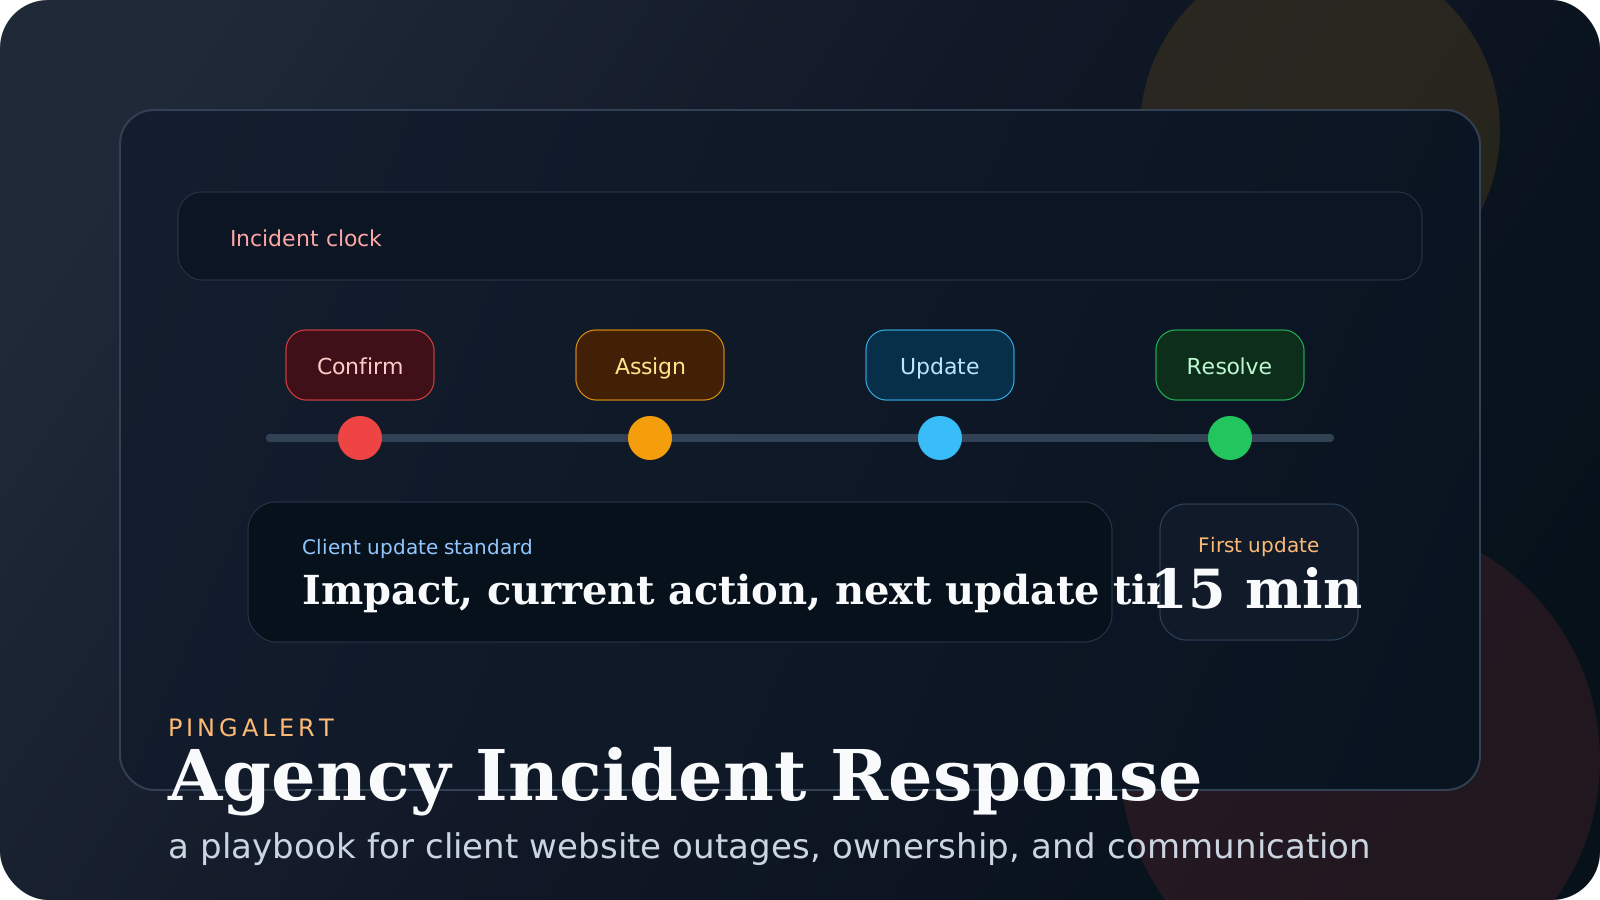
Agency Incident Response Playbook: How To Handle Client Website Outages Without Chaos
A practical incident response workflow for agencies managing client website and API outages across multiple accounts, channels, and stakeholders.
Client Reporting for Agencies: Uptime Reports That Prove Value Each Month
How agencies can turn uptime monitoring data into monthly client reports that show reliability, response quality, and next-step accountability.
Website Monitoring for Agencies: How To Cover Client Sites Without Alert Chaos
A practical website monitoring playbook for agencies managing multiple client sites, APIs, alerts, and retention risk across one portfolio.
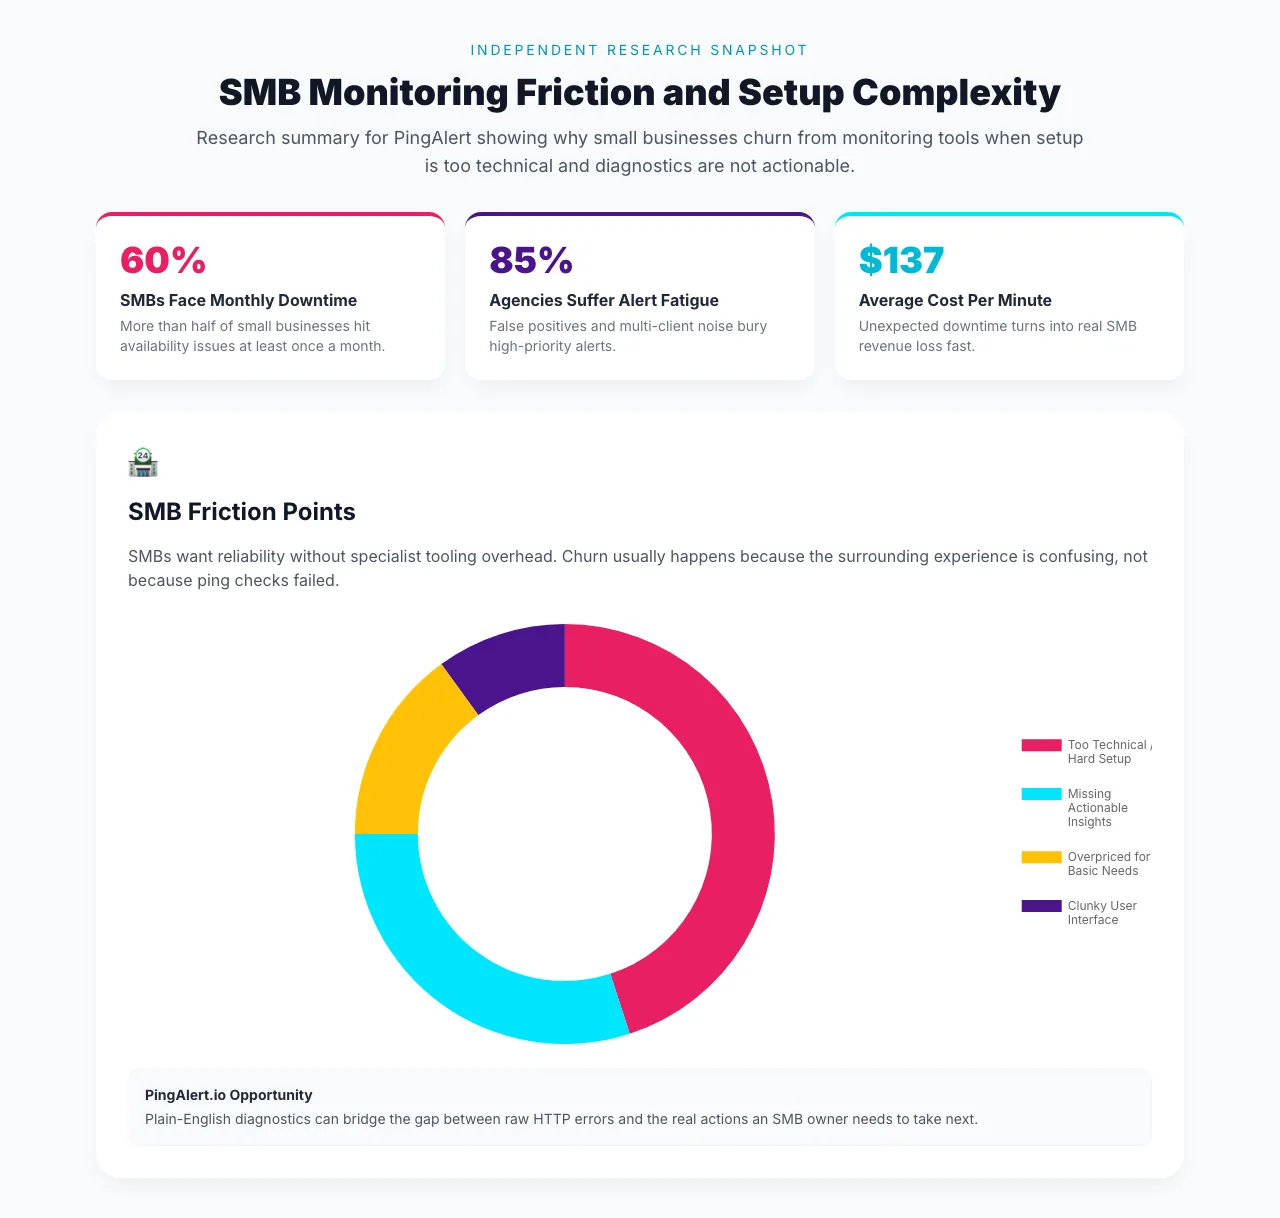
Why SMBs Leave Website Monitoring Tools: Research on Setup Friction and Plain-English Diagnostics
Independent research shows SMB monitoring churn is driven more by technical setup friction and missing actionable diagnostics than by the core uptime check itself.
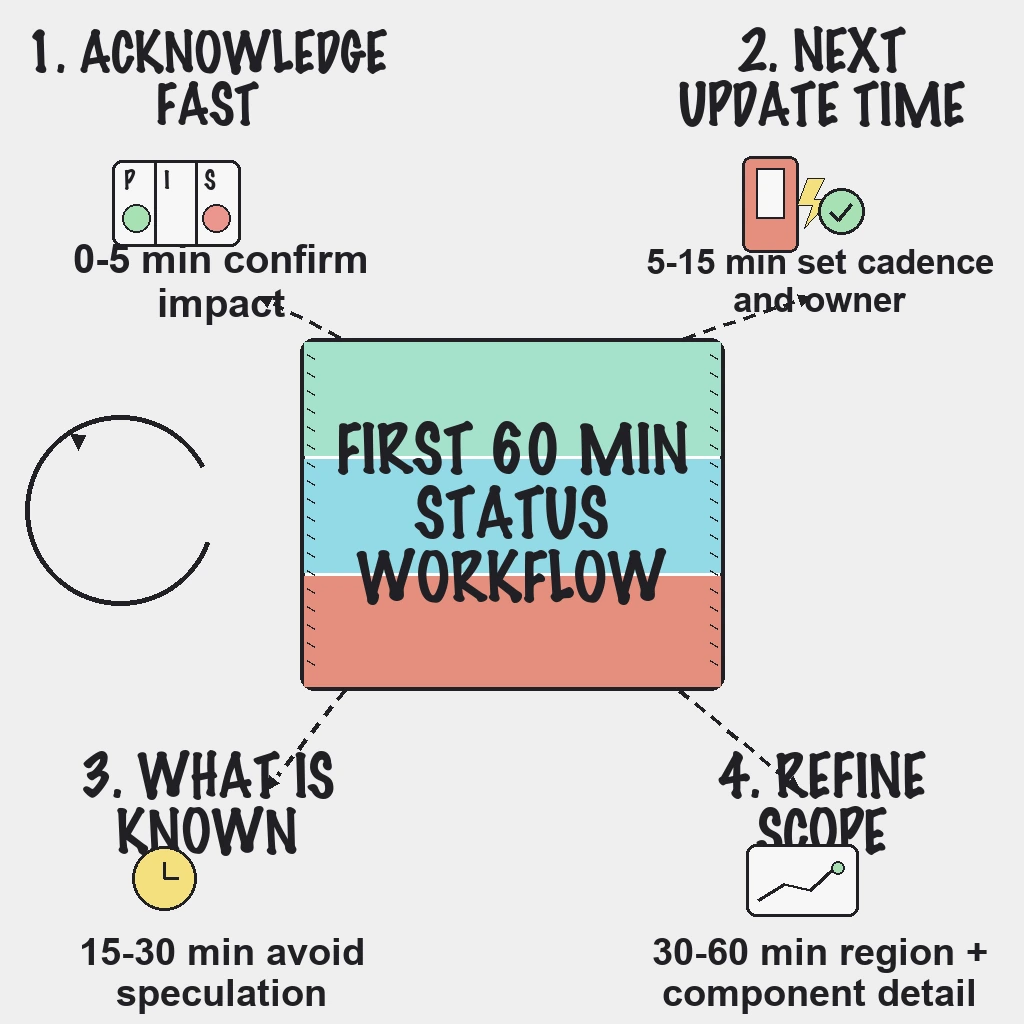
Status Page Incident Communication Workflow: What to Publish in the First 60 Minutes
A status page incident workflow: what to publish in the first 60 minutes, who owns each update, copy-ready templates, update cadence and how to close well.
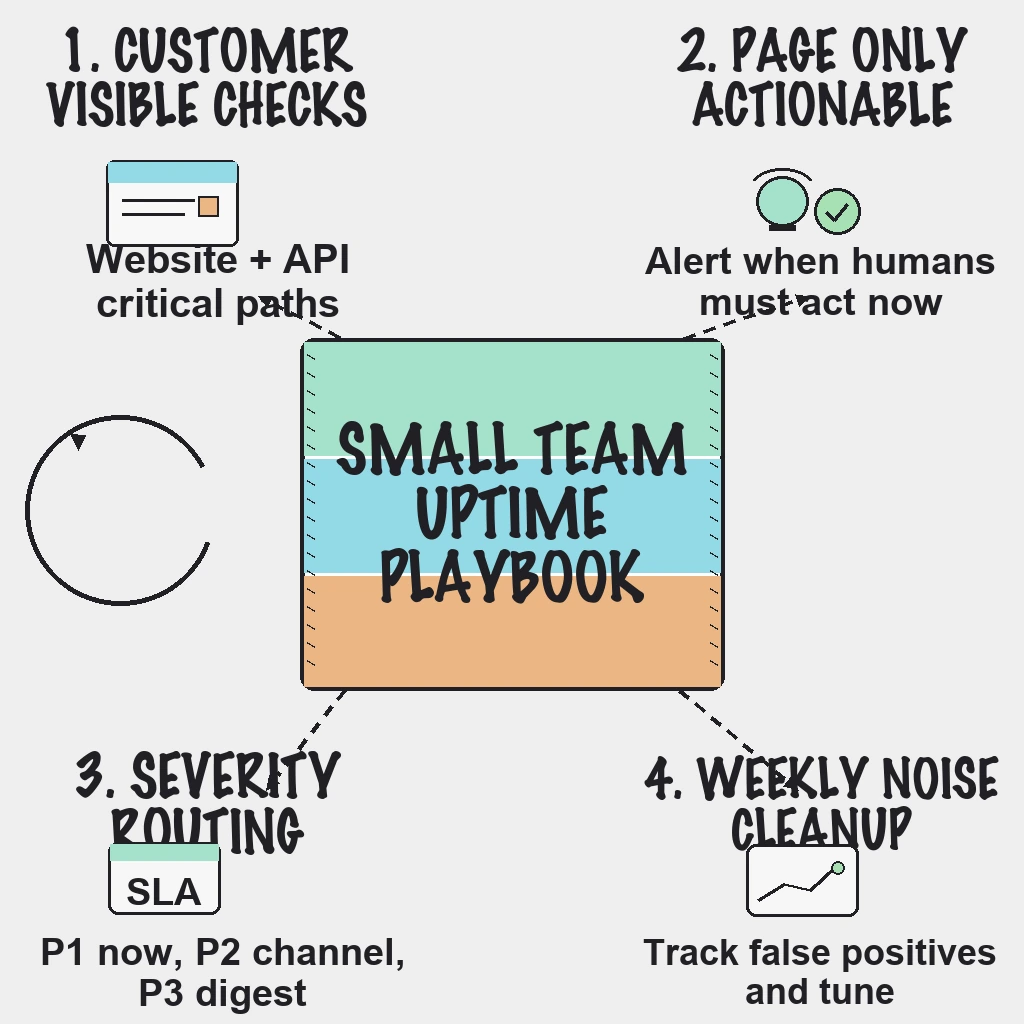
Uptime Monitoring for Small Teams: Reduce Alert Fatigue Without Missing Real Incidents
Uptime monitoring for small and lean SaaS teams: what to check first, how to page only on real outages, a 45-minute setup and a runbook to keep noise down.
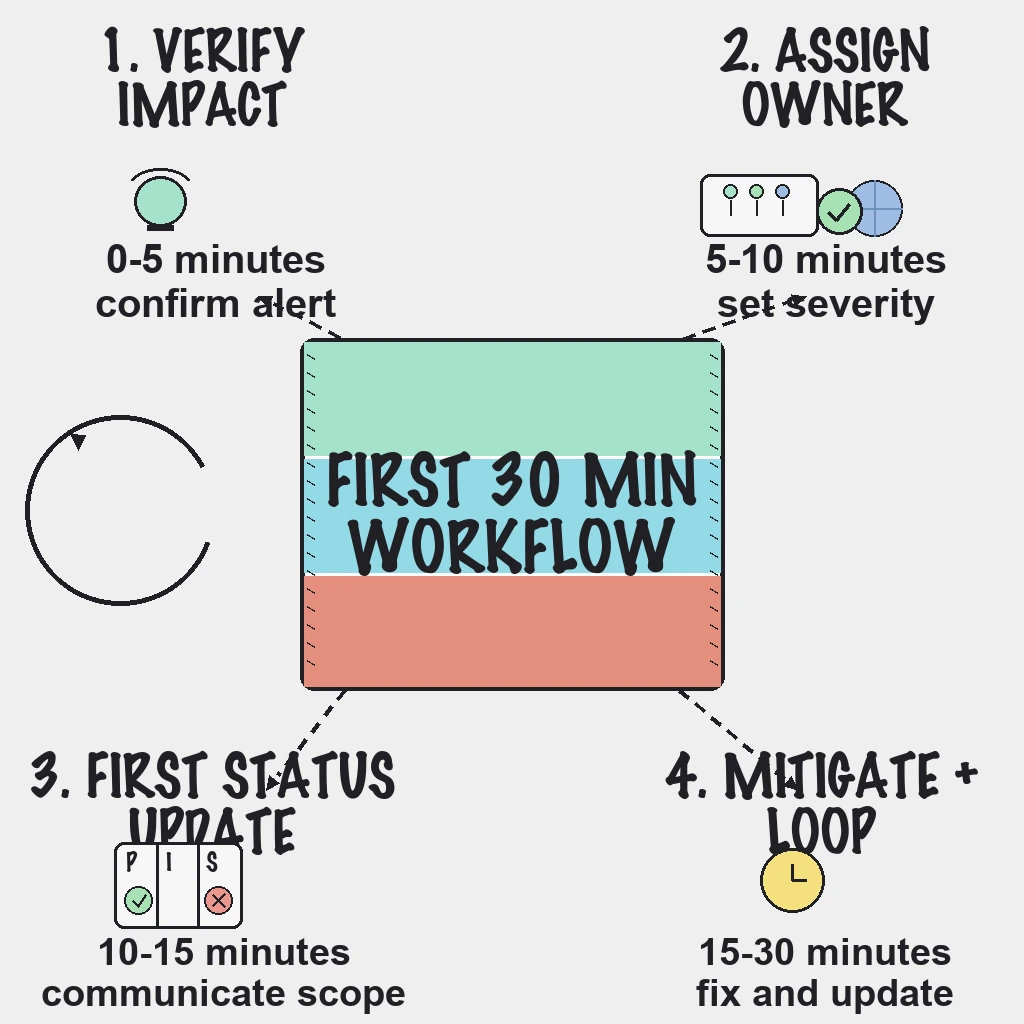
Incident Management Workflow for SaaS: The First 30 Minutes and Follow-Through to Closure
An incident management workflow for SaaS teams: what to do in the first 30 minutes, then how to follow through from stabilization to closure and review.
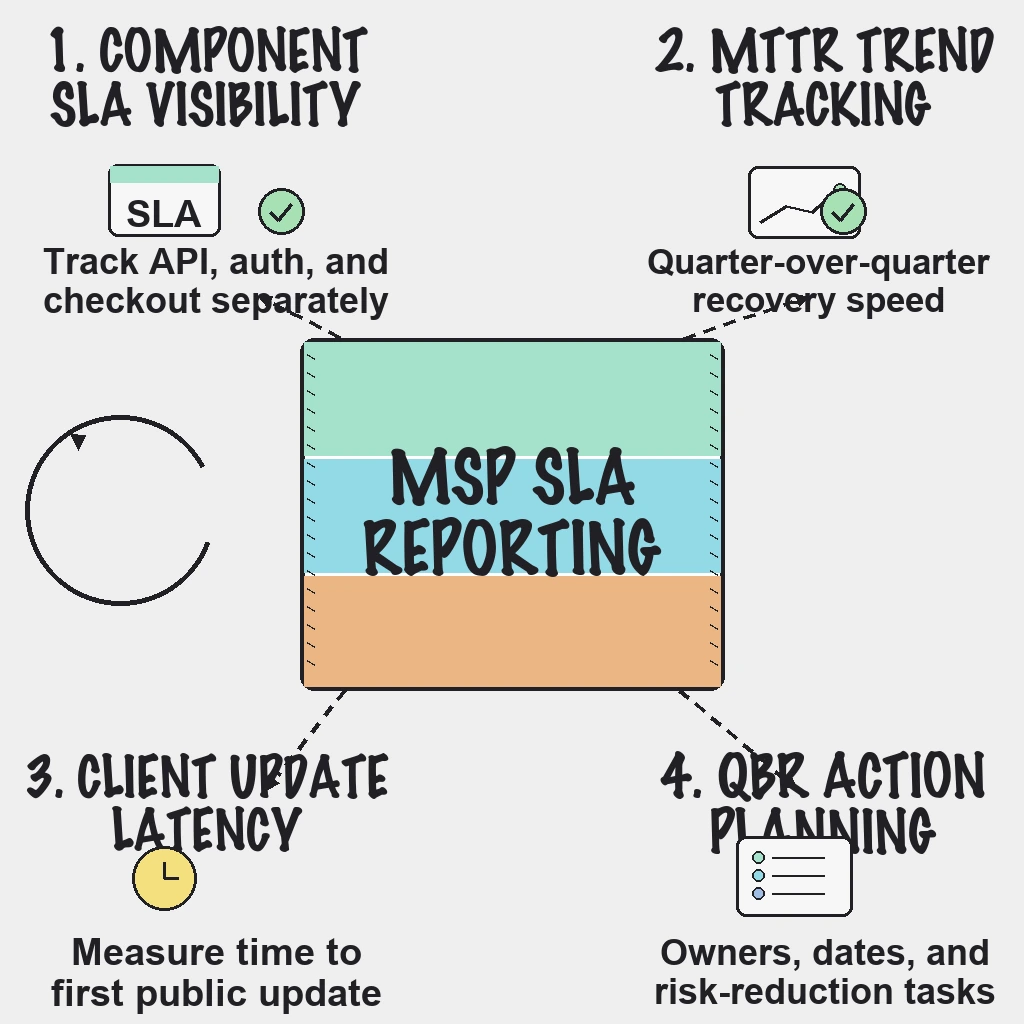
MSP SLA Reporting for Uptime Monitoring: QBR Metrics Clients Actually Care About
How MSPs can build SLA reports that improve client trust and renewals using MTTR, false-positive rate, and incident communication metrics.
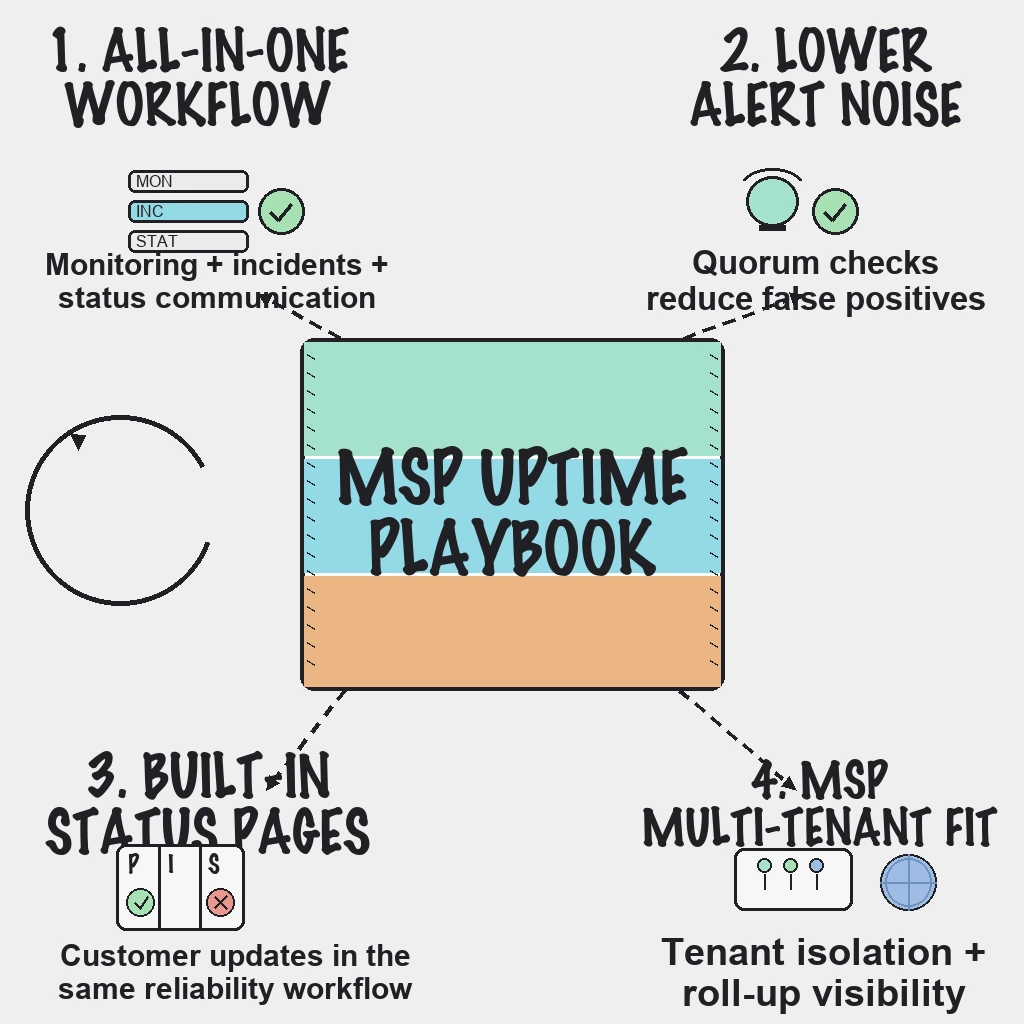
MSP Uptime Monitoring Playbook: Multi-Tenant Operations Without Alert Fatigue
A practical MSP uptime monitoring playbook for multi-tenant operations, lower alert noise, faster incident response, and better client communication.
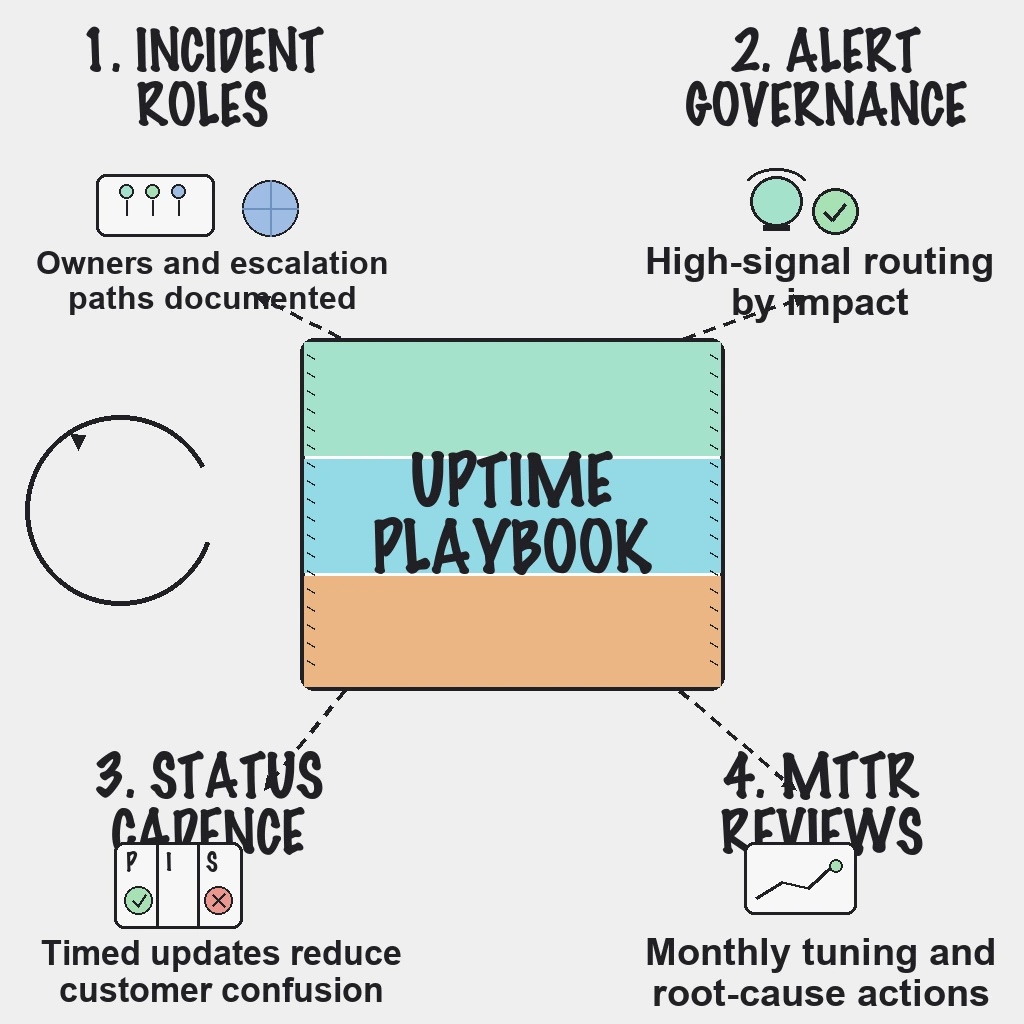
Uptime Monitoring: A Practical Playbook for Uptime Reliability and Business Growth
A practical uptime monitoring playbook: why uptime drives revenue, search and trust, what to check first, how to route alerts and what to tune monthly.
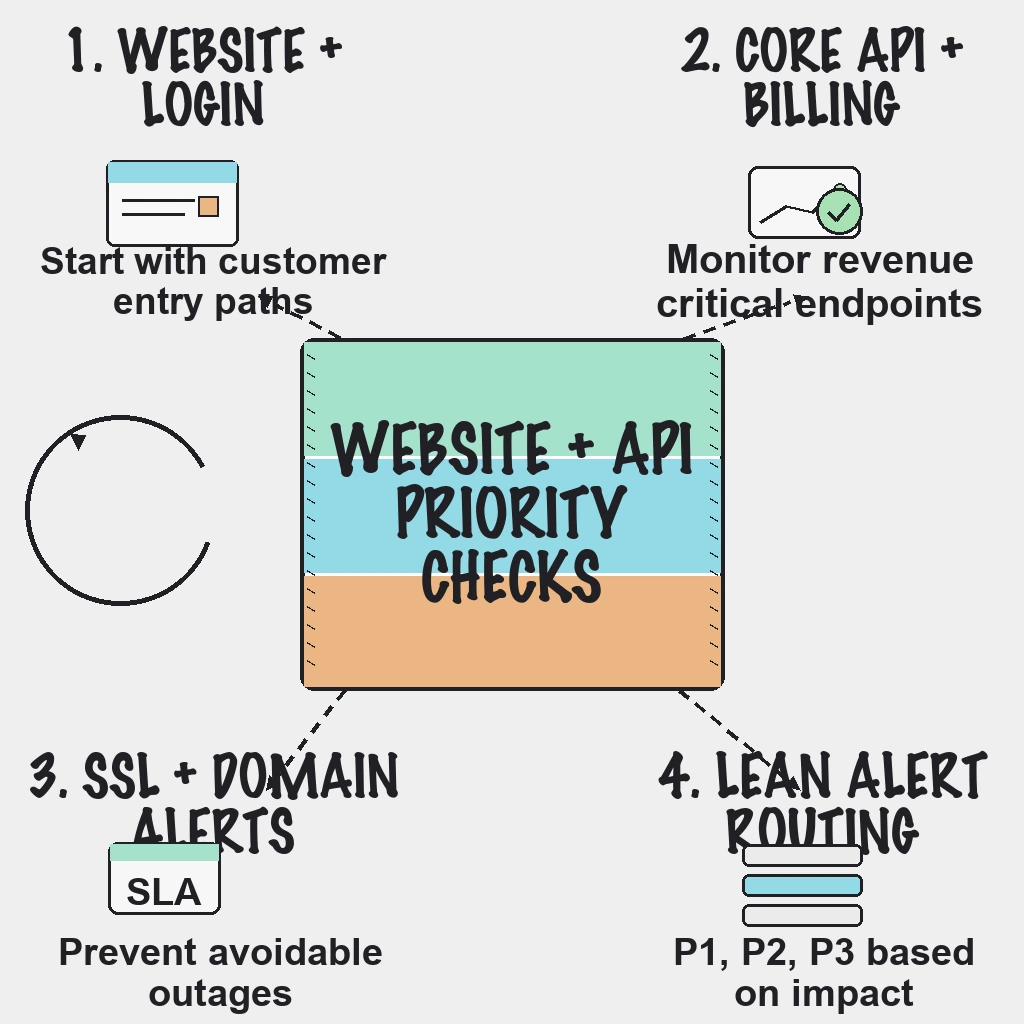
Website and API Uptime Monitoring for Lean Teams: What to Monitor First
A lean priority checklist for website and API uptime monitoring so small teams can detect real outages early without noisy over-monitoring.
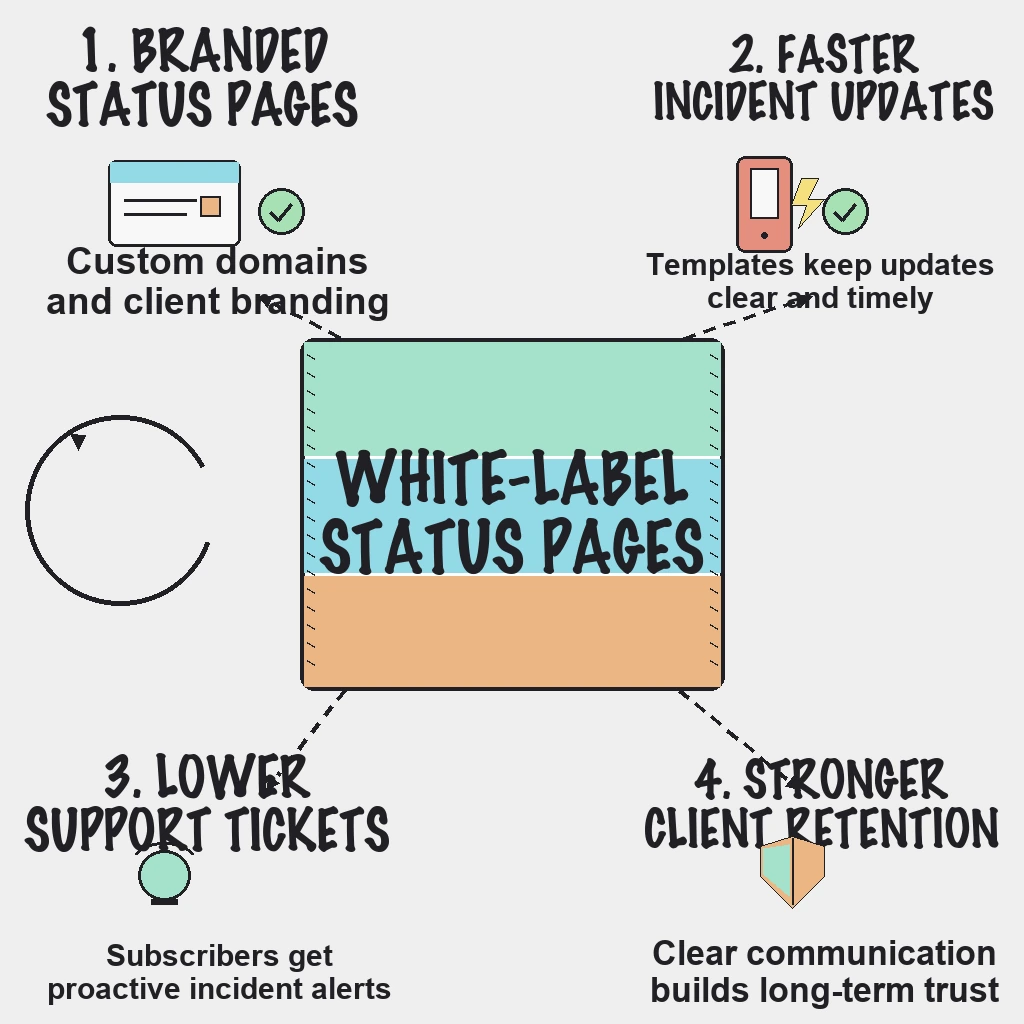
White-Label Status Pages for Agencies: Reduce Churn During Incidents
A practical agency playbook for white-label status pages that reduce client escalations, protect retainers, and improve incident communication.
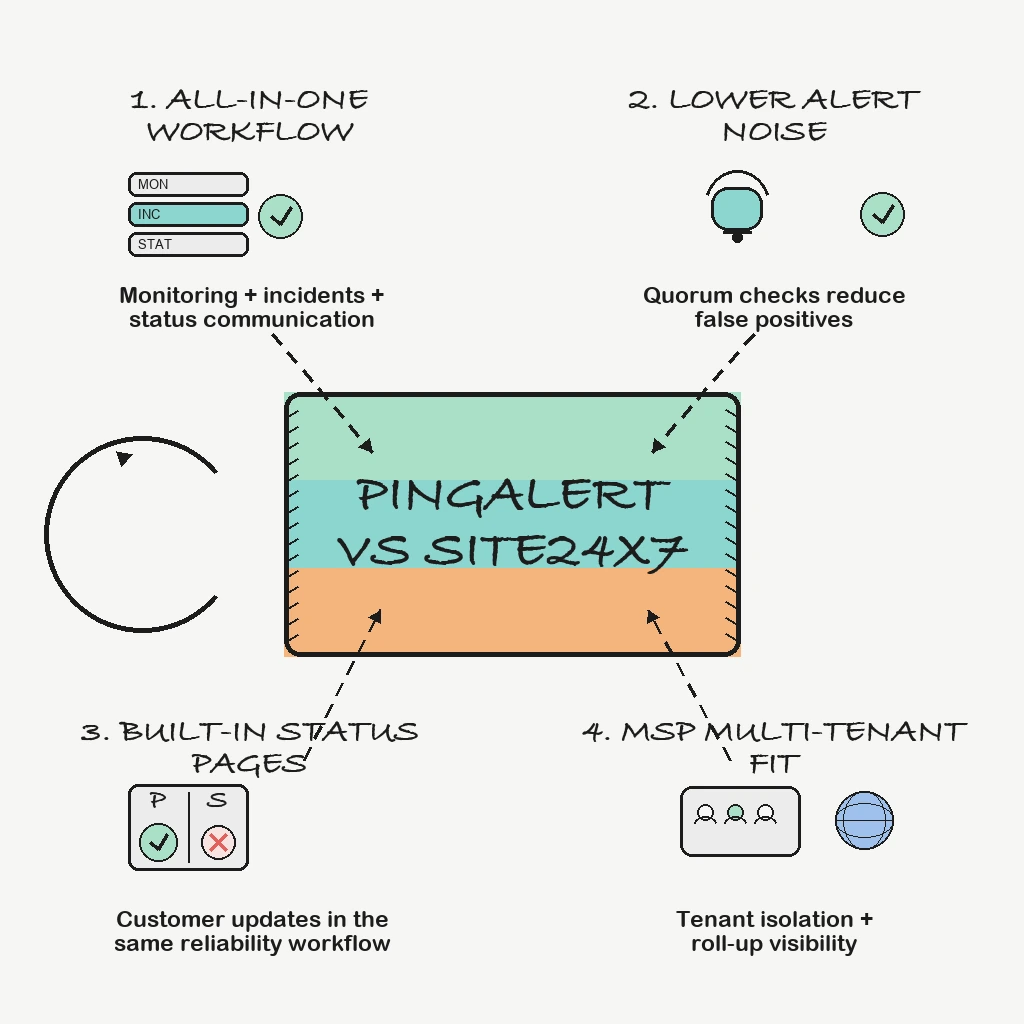
PingAlert vs Site24x7: What Changes for Uptime-Focused Teams
A practical comparison of PingAlert and Site24x7, with a focus on uptime operations, alert quality, incident response, and customer communication.
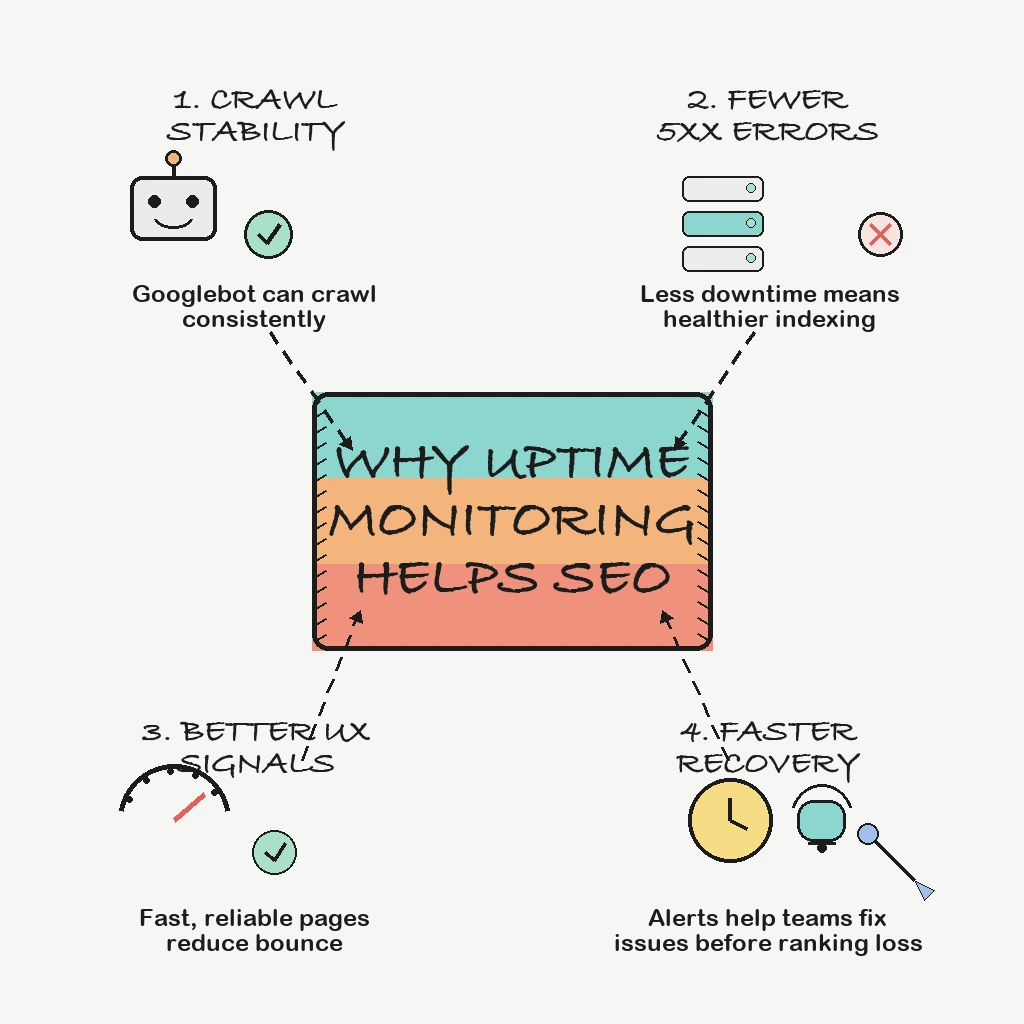
Why Uptime Monitoring Is Important for SEO (and How It Helps Rankings)
Uptime monitoring protects your SEO by preventing crawl failures, reducing prolonged 5xx errors, and helping teams fix issues before rankings and traffic drop.
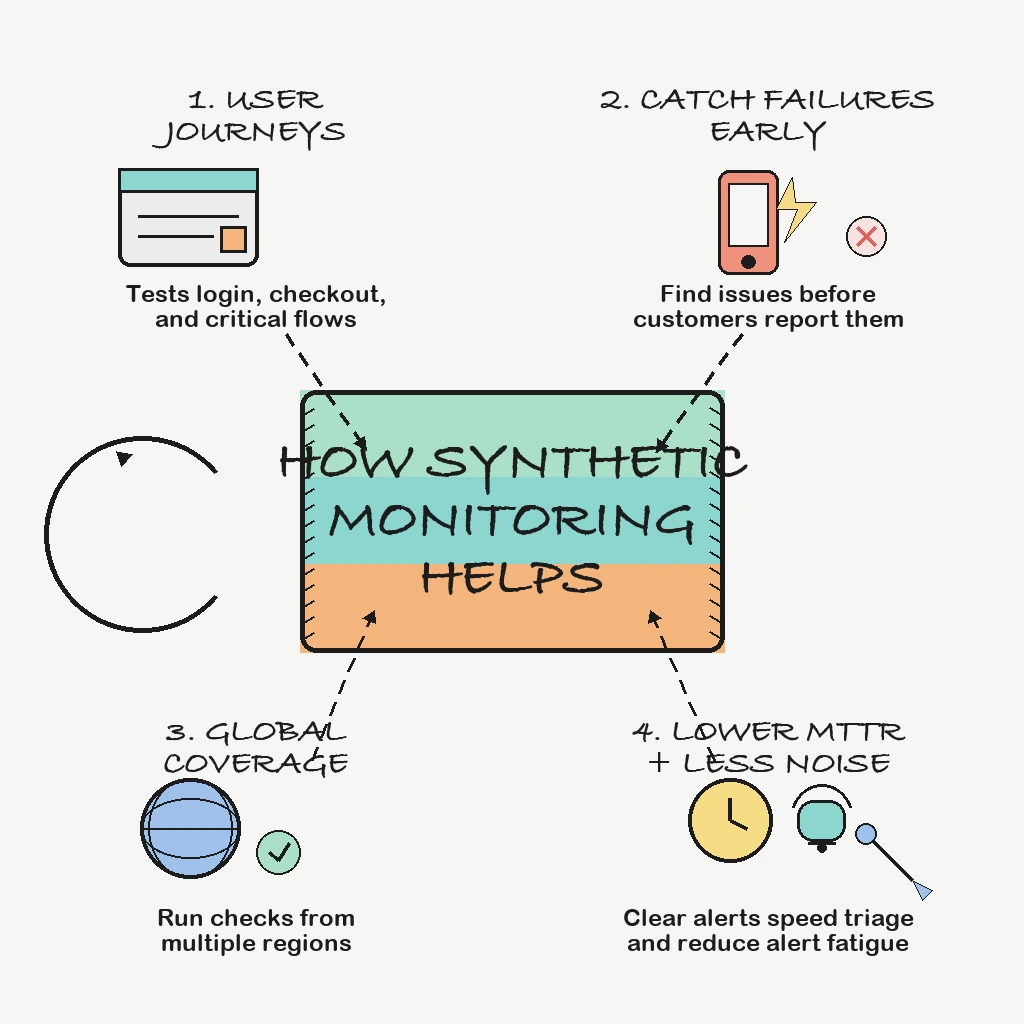
How Synthetic Monitoring Helps (and Why It Is Important)
Synthetic monitoring helps teams detect user-facing failures early by testing key journeys like login, checkout, and API flows before real customers are affected.
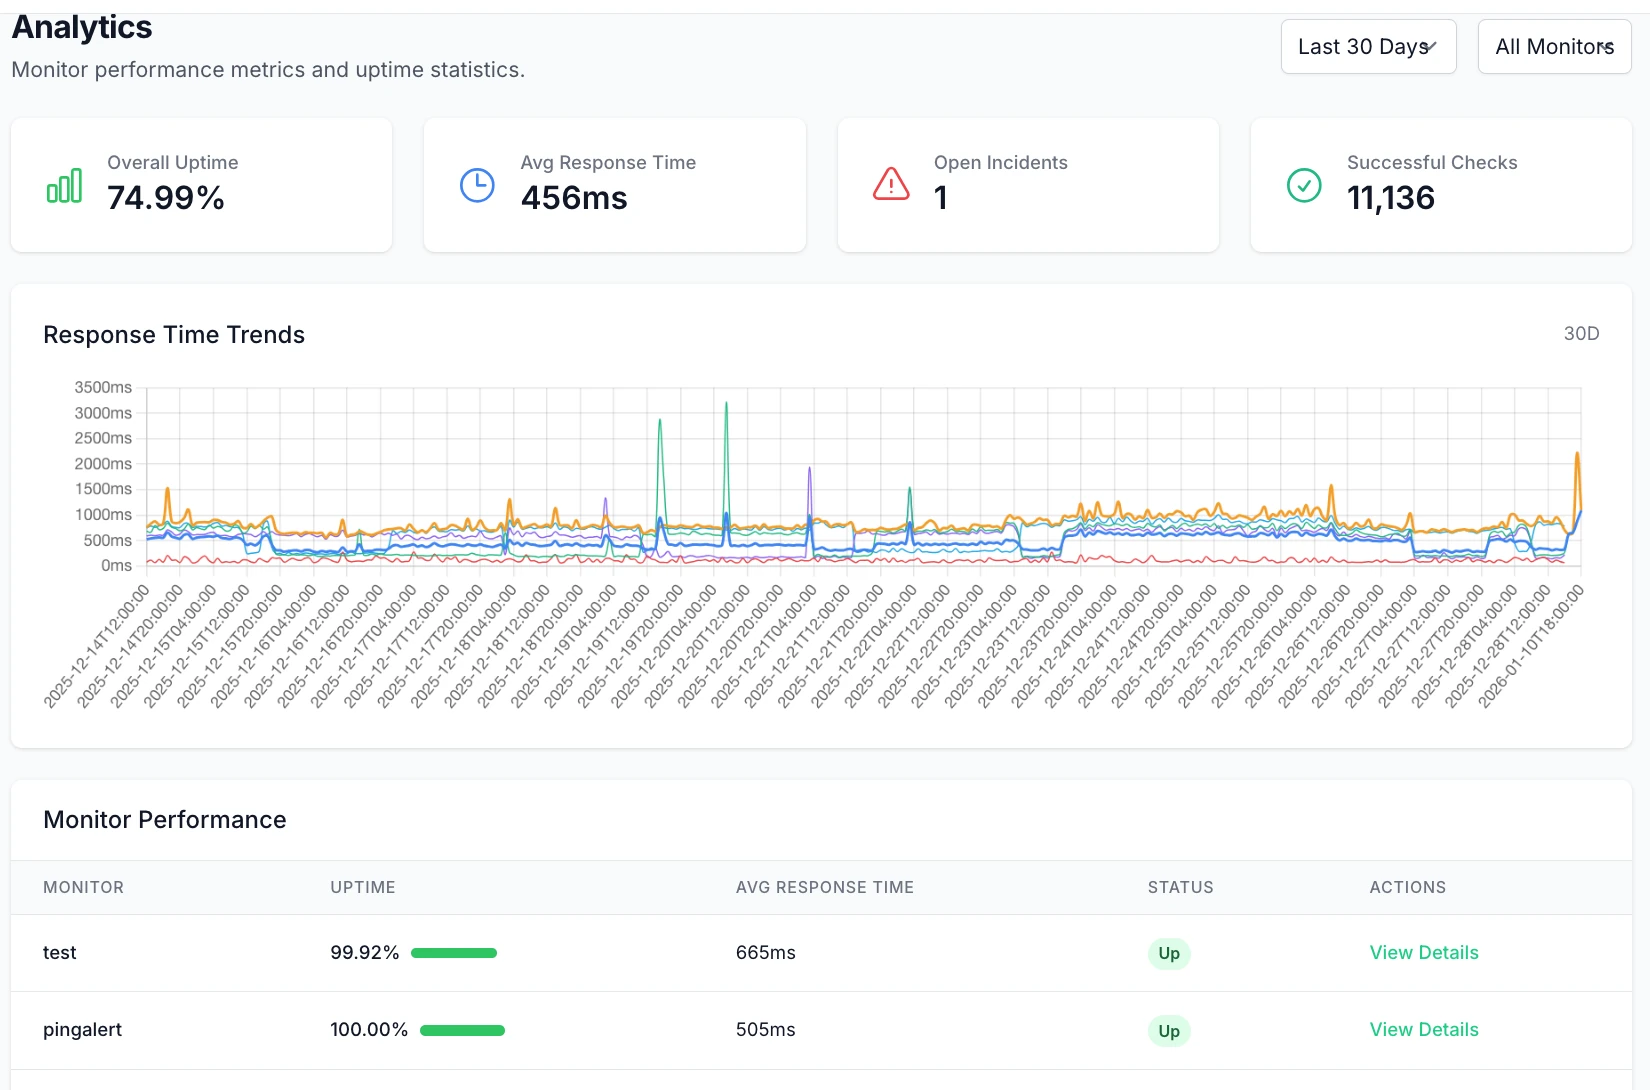
Global Website Uptime Monitoring with PingAlert – Fast, Reliable, and Noise-Free
Discover how global website uptime monitoring with PingAlert delivers synthetic checks from multiple regions, noise-free alerts, branded status pages, and practical incident workflows.
Status Page Best Practices for Customer Trust
A practical guide to status pages customers trust: component design, when to post, update cadence, plain language and post-incident summaries.